Where you’re losing
The diagnostic that turns the headline score into a punch list. Answers: which questions am I missing, and on which engine?
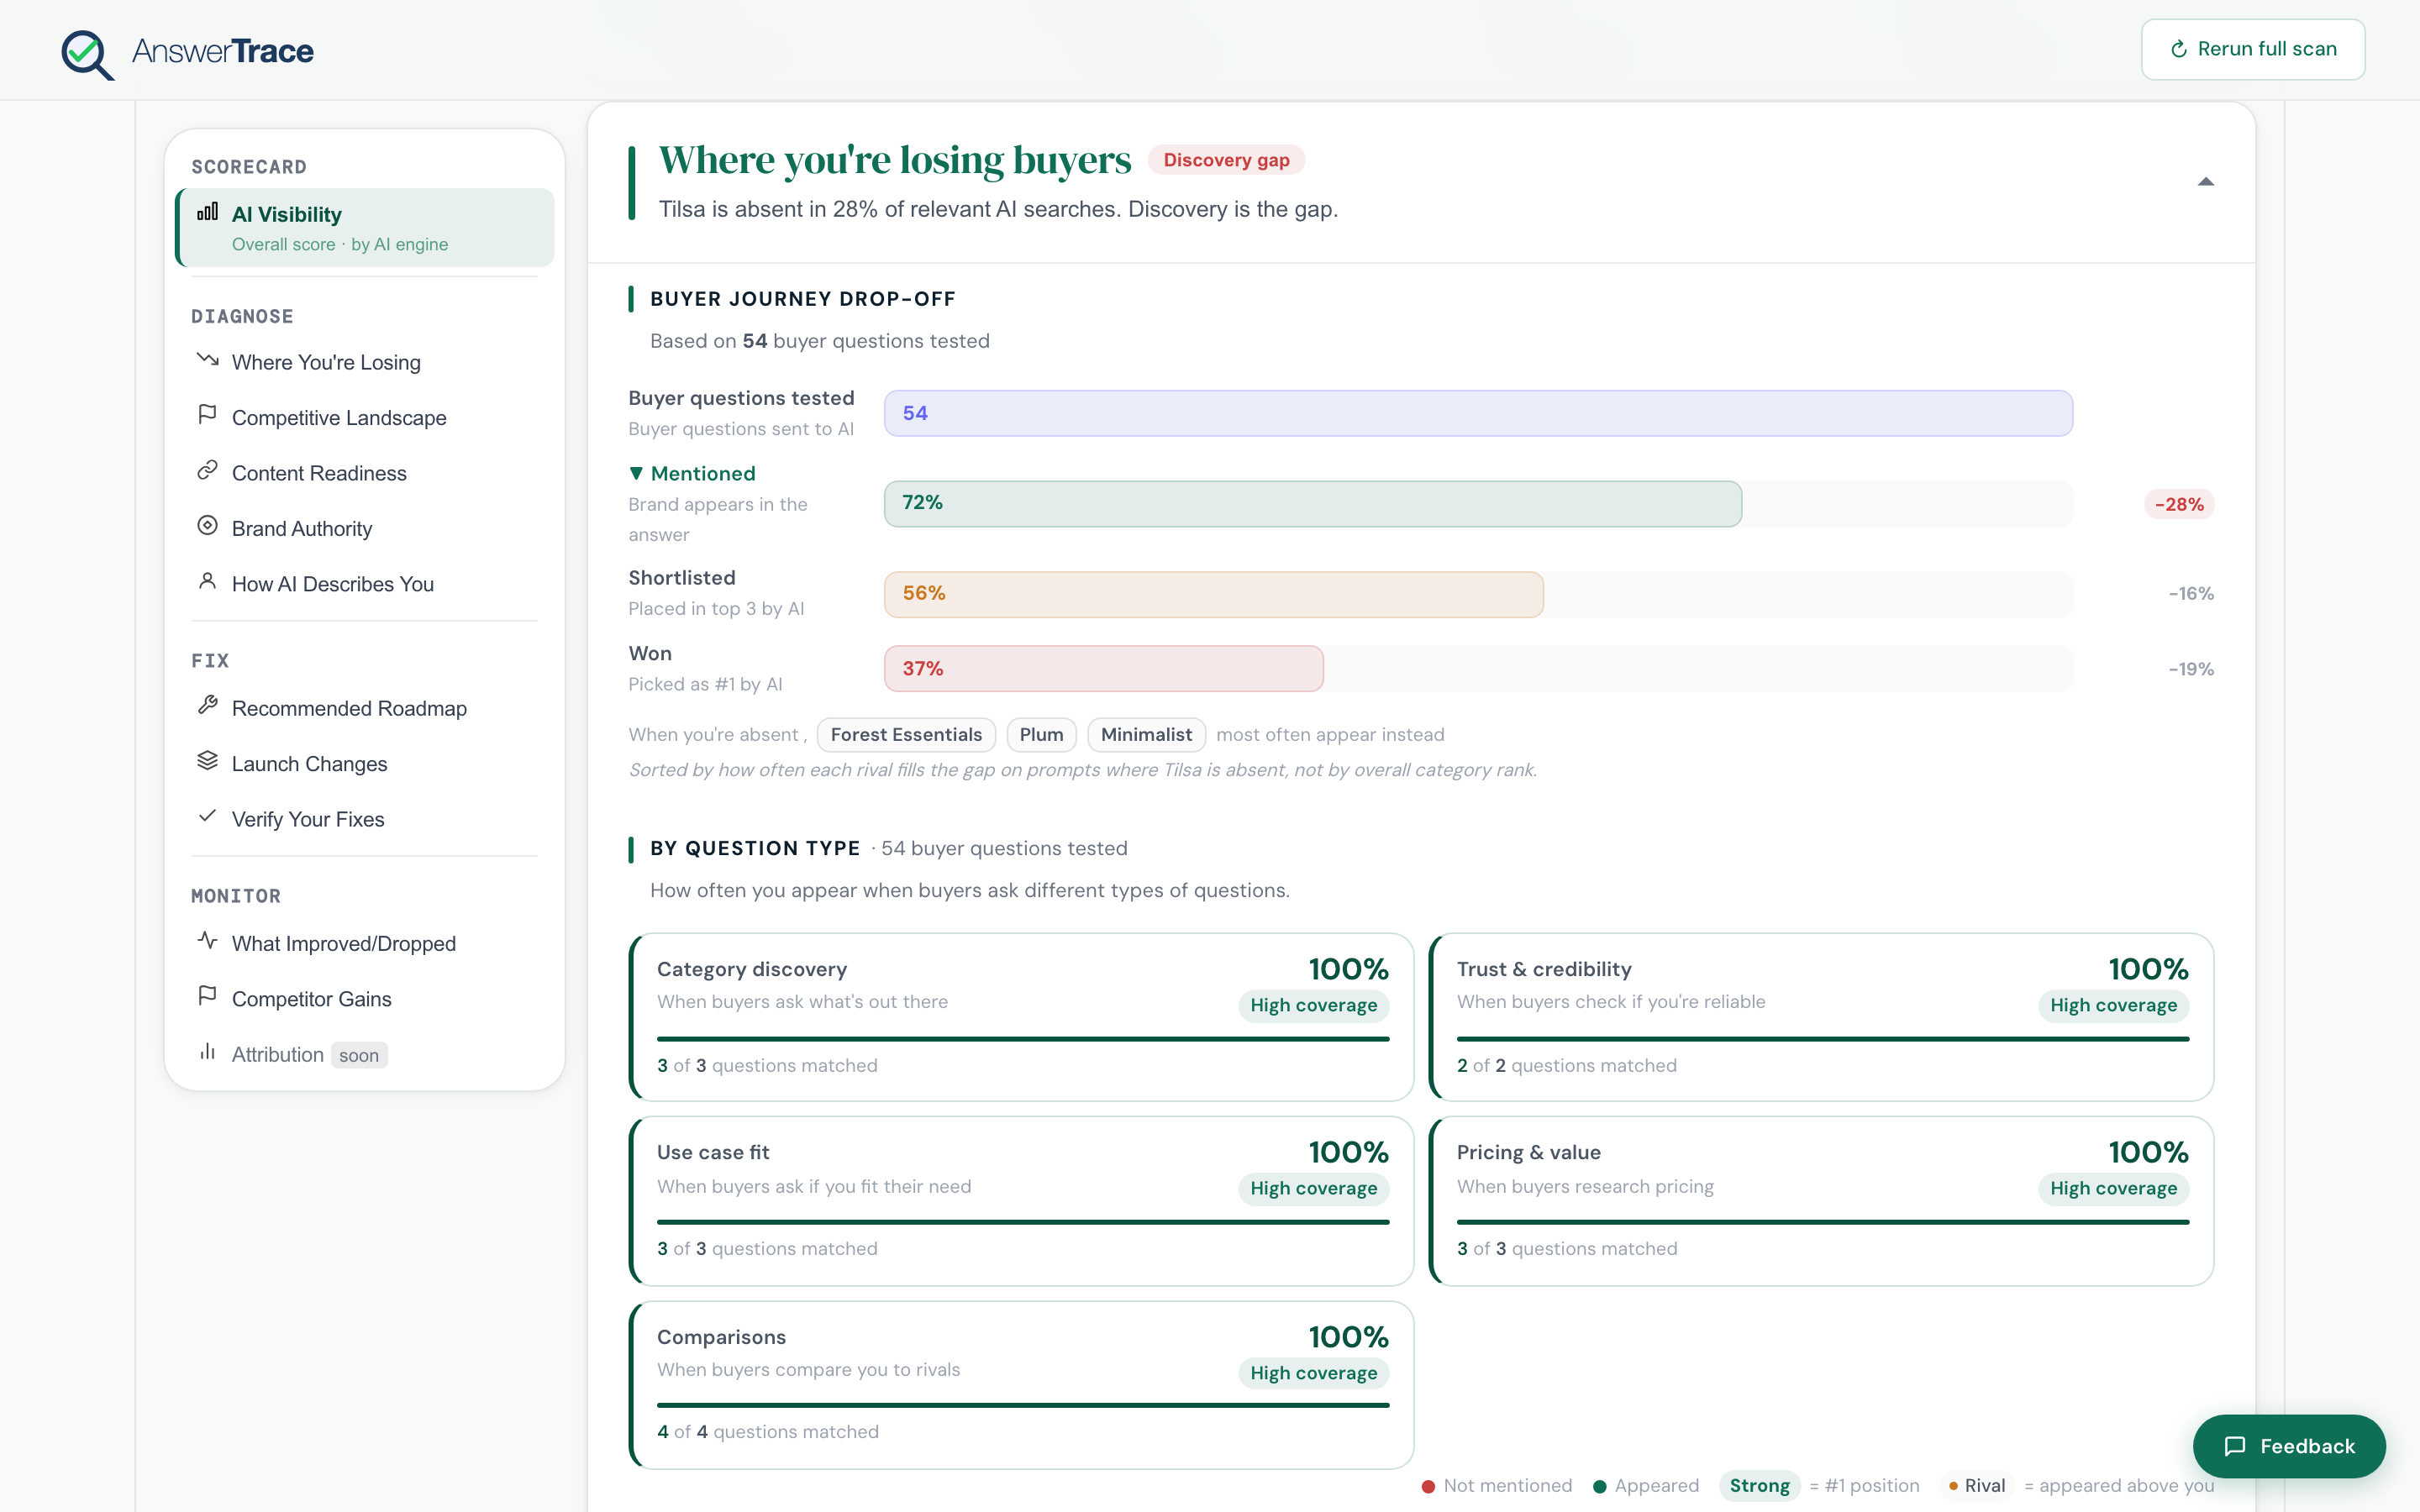
The buyer-journey funnel
Inside this section, AnswerTrace draws the four-stage funnel:
- Buyer questions tested, the prompts in your scan
- Mentioned, your brand showed up in the answer
- Shortlisted, your brand was in the top three
- Won, your brand was the #1 choice
This is the per-section breakdown. The shorter three-stage funnel on the Scorecard (Discovery, Shortlist, Win) is the headline view; this one expands the first stage so you can see how many prompts even reached the AI answer.
The intent grid
Every prompt is tagged with a buyer-intent so the section can show coverage per category. The tags used in the report are:
| Intent | What it covers |
|---|---|
| Brand | Buyers searching your brand by name |
| Core | Open-ended “best X” or “top Y” category discovery |
| Use-case | ”Best for D2C”, “best for SMB”, workflow-led questions |
| Commercial | Pricing and value questions |
| Trust | Reliability, support, reviews, credibility |
| Competitor | ”Brand A vs Brand B” head-to-heads, alternatives |
Indian-language prompts (Hindi, Hinglish, Tamil on Pro) carry a separate language tag in addition to the intent tag, so the same Core question in Hinglish is counted against Core, not against a “Regional” bucket.
If you’re 90% covered on Brand prompts and 10% on Core, AI knows you exist but doesn’t pick you when buyers don’t type your name. That’s the most common gap.
Per-engine breakdown
Below the funnel, a per-engine matrix shows where each engine drops you, with the count of prompts the engine drops at each stage and the score per engine. The matrix is data, not editorial diagnosis; the Recommended roadmap is where the engine-specific causes turn into actions.
What this means for you
This section is the diagnostic. The prescription lives in Recommended roadmap, which reads the same gaps and surfaces them as findings grouped into This week / This month / This quarter buckets.